Predictive Maintenance Analytics: Plant Managers' 30–50% Downtime Cut
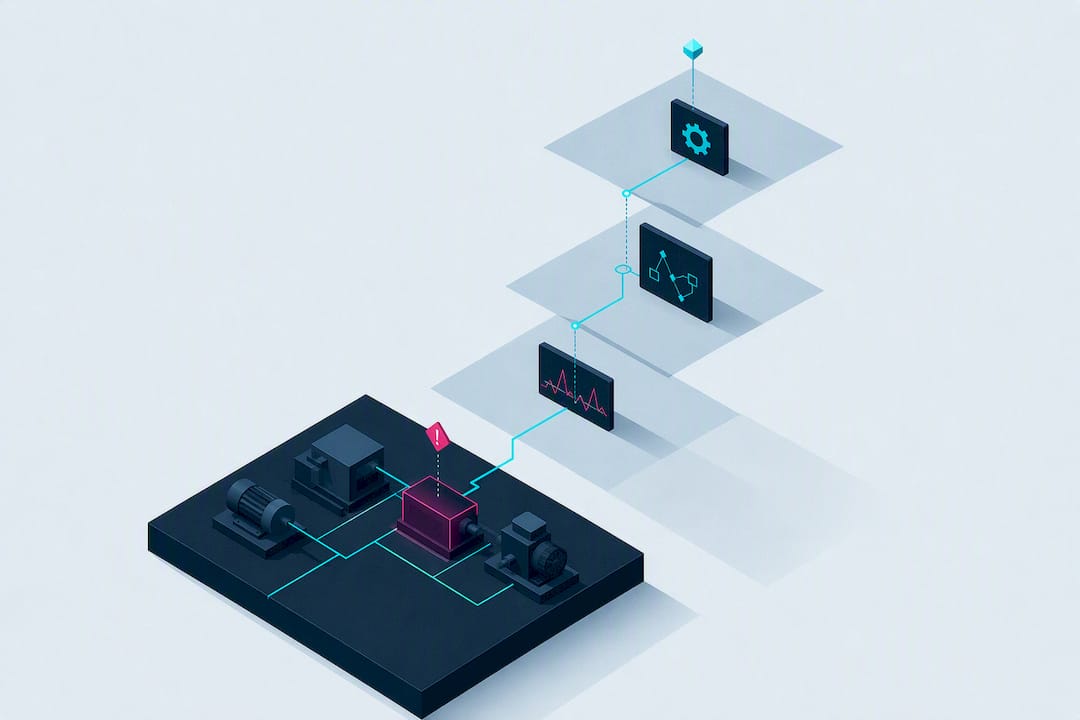
Predictive maintenance analytics uses sensor data, historical records, and machine learning to flag equipment problems before they cause downtime. The industry quotes a 30 to 50 percent cut in unplanned downtime for programs that fully adopt it — and that range is worth knowing, mostly so you can ask every vendor the question that matters: measured on whose plant? Because here's the uncomfortable truth about this category: most predictive maintenance programs don't fail on the model. They fail on the four things the brochure skips — the sensors you were told to buy, the thresholds that cry wolf, the scores nobody can audit, and the predictions that never change a schedule. This guide covers all four, and how to buy around them.
TL;DR:
- The market's default playbook — instrument first, set thresholds, trust the score — is precisely the sequence that kills pilots. Your PLCs and historians already hold years of usable signal; the gap is reading it, not collecting more.
- Generic thresholds are the false-alarm factory: a limit that's right for the average machine is wrong for every actual machine. Demand per-machine, per-recipe learned baselines with context (recipe, load, shift) built in.
- A prediction without evidence is a rumor with a decimal point. Every alert should carry its signal, its baseline, and a comparable historical event — and calibrated uncertainty, not false precision.
- A prediction that doesn't change the schedule is a horoscope. The maintenance window has to be planned inside the production plan, with a signed work order and a measured outcome.
- Industry ranges like 30–50% are context from other people's plants, not promises about yours. Any number quoted before your data has been read is a scenario — a serious vendor labels it as one.
Table of Contents
- What Predictive Maintenance Analytics Is and How It Works
- Four Ways the Market Sells It — and Where Each One Breaks
- Data Requirements and Signal Types
- Modeling Approaches: Anomaly Detection, Diagnostics, and Prognostics
- Benefits, ROI Ranges, and Realistic Timelines
- How Atherya Implements Predictive Maintenance Analytics
- The Questions to Ask Any PdM Vendor
- Implementation Roadmap: Pilot, Validate, Scale
- What I'd Prioritize First
- Start With a Data-Led Assessment, Not a Blank Slate
- Sources
- FAQ
What Predictive Maintenance Analytics Is and How It Works
Predictive maintenance analytics turns raw operational data into a specific answer: which machine is likely to fail, when, and why. That's a different job than condition monitoring, which just measures machine state, or preventive maintenance, which swaps parts on a fixed calendar regardless of actual wear. Condition monitoring gives you a dashboard of readings; predictive maintenance analytics gives you a forecast — and, if it's any good, a decision.
The pipeline runs in four stages:
- Data collection. Vibration sensors, PLCs, SCADA historians, CMMS logs, ERP records, and operator notes all feed the same model. Hold on to this fact, because the whole first attack below hangs on it: most plants already generate this data. The gap is connecting it, not collecting it.
- Data engineering. Signals arrive at different rates — a vibration sensor every second, a CMMS entry once a week — so the system synchronizes timestamps, tolerates sensor dropout, and extracts the features that actually correlate with wear.
- Modeling. Anomaly alerts (something changed), fault classification (this looks like bearing wear), or remaining-useful-life estimates (this pump has weeks, not months) — depending on what your data can honestly support.
- Action. A prediction that never reaches a technician — or never moves a production schedule — is worthless. This is where most projects quietly die, and it's the market's least-discussed failure mode, so it gets its own attack below.
Four Ways the Market Sells It — and Where Each One Breaks
Sell number one: "Start by instrumenting." The sensor catalog arrives before the first insight does. Months of retrofits, per-point costs, production interruptions to mount hardware — and at the end, a model that has beautiful new data and still doesn't know your plant, because the years of history that actually define each machine's normal are sitting unread in the historian. Audit what your PLCs and SCADA already record before buying anything: most plants have years of usable signal — current draw, cycle times, temperatures, counts — that nobody has ever queried for maintenance purposes. The most expensive sensor is the one you didn't need.
Sell number two: "Set the thresholds." One alarm limit per machine family, straight from the manual or the fleet average. Here's what that arithmetic guarantees: a threshold that's right for the average machine is wrong for every actual machine — too tight for the tired one, too loose for the healthy one, blind to the fact that a vibration spike during a high-load recipe change is a different event than the identical spike at steady state. The result has a name every maintenance lead knows: alarm fatigue. Enough false positives and the whole shift learns to click dismiss — and the one real warning sails through with the noise. Generic thresholds don't detect failures. They train your team to ignore alarms.
Sell number three: "Trust the score." Health index 73. Confidence: high. Evidence: none. When a technician asks "why?" and the answer is a shrug with a color code, the system has one wrong call left before it's ignored forever — and operators are right to ignore it, because an unauditable score is indistinguishable from a guess. Calibration makes it worse: a model that says "80% confident" and is right half the time is actively teaching people to distrust it. A prediction without evidence is a rumor with a decimal point.
Sell number four: "The alert is the product." The prediction fires, lands in a dashboard, and dies there — because the PdM tool doesn't know the production plan exists. The maintenance window it implies collides with a delivery, planning won't release the machine, the failure arrives on schedule, and the post-mortem concludes "the tool predicted it," as if that were a defense. Prediction isolated from scheduling isn't foresight; it's documentation of the disaster in advance. A prediction that doesn't change the schedule is a horoscope.
THE MARKET SELLS PREDICTION AS A SENSOR CATALOG AND A SCORE. THE JOB IS THE CONSEQUENCE: A PLAN THAT CHANGES BEFORE THE MACHINE BREAKS.
Data Requirements and Signal Types
Good predictions start with the right signals, sampled at the right frequency, with enough history to establish each machine's own normal.
Core sensor types and what they catch:
- Vibration — bearing wear, misalignment, imbalance, long before they're audible.
- Temperature — friction, lubrication failure, electrical issues in motors and drives.
- Current draw — mechanical load changes and early motor degradation, with no new hardware at all.
- Pressure — hydraulic and pneumatic systems where leaks and blockages build gradually.
- Acoustic — high-frequency events, like early gear wear, that vibration sometimes misses.
Sensor readings alone tell an incomplete story. Context signals — which recipe was running, which shift, how loaded the line was, recent quality results — often explain why a reading spiked, and models that ignore context are false-alarm machines (see sell number two). The same spike, different recipe, different meaning: a model that can't tell them apart isn't modeling your plant, it's modeling a brochure plant.
On sampling: match the rate to the failure mode, don't chase the maximum your budget allows. And build in tolerance for gaps — sensors drop offline, PLCs reboot, CMMS entries land late. A system that breaks on a data gap will fail in production, not in testing.
Integration with your CMMS and ERP is where governance starts: who approves a model-generated work order, how alerts are logged for audit, and how you track which predictions were acted on versus ignored. That trail is your evidence when someone asks why a machine failed anyway — and it's the raw material for measuring whether the program is actually paying (more on that below).
Pro Tip: Before buying a single new sensor, audit what your PLCs and SCADA are already recording. Most plants have years of usable signal sitting in historian databases nobody has queried for maintenance purposes.
Modeling Approaches: Anomaly Detection, Diagnostics, and Prognostics
Three approaches, three different data appetites — and picking one your data can't support is the most common technical mistake in early PdM projects.
- Anomaly detection (unsupervised) flags when a machine deviates from its own historical baseline. No labeled failures needed, fastest to deploy — it can't name the fault, but it's honest about that.
- Fault classification (supervised) names the failure mode — bearing wear versus misalignment versus lubrication — but needs a labeled dataset of past failures large enough to train on. For rare failure modes, most plants simply don't have it, and pretending otherwise produces a classifier that hallucinates diagnoses.
- Prognostics (remaining useful life) estimates time to failure. Highest value, hungriest for data — run-to-failure history plus calibrated uncertainty, not a naked point estimate. An RUL number without an honest error bar is sell number three wearing a lab coat.
A modular architecture separating data, modeling, and a cost-aware decision layer lets you start humble and upgrade without rebuilding.
Whatever you deploy, evaluate it on four numbers: lead time (how far ahead the alert fired), false-alarm rate (how many alerts were nothing), calibration (does "80% confident" come true 80% of the time), and decision utility (did acting on it beat doing nothing, in money). A model with excellent accuracy and poor calibration erodes trust faster than a mediocre model that's honest about its uncertainty — technicians forgive "I'm not sure"; they never forgive confident nonsense.
When failure history is scarce — the normal state for critical assets that rarely fail — start with anomaly detection against learned baselines and physics-informed limits. Don't wait years to accumulate failures you're actively trying to prevent; the structured decision frameworks in the literature all land on the same staircase: alerting first, diagnosis when the labels exist, RUL-plus-decisioning when the pipeline has earned it.
Benefits, ROI Ranges, and Realistic Timelines
The documented ranges: 30 to 50 percent less unplanned downtime in facilities that fully adopt, failures flagged 30 to 90 days out in reported cases, payback within months to a year and a half. Useful context — and here is exactly how to use it: as a question, never as a promise. Those figures are aggregates from other people's plants, with other people's data quality and other people's adoption discipline. Any vendor who quotes them as your expected outcome before reading a byte of your history is reciting someone else's bedtime story with a percentage in it. The honest sequence runs the other way: read your data first, find what's actually there, and state projections as scenarios until your own baseline confirms them.
What the ranges are good for: holding your own pilot accountable. If your results fall well short after two quarters, the culprit is usually data quality or workflow integration — the last stage of the pipeline — not the model.
The assets that pay back fastest share three traits: expensive to stop, failure modes that show precursor signals (bearings, pumps, motors), and enough current pain that the baseline is obvious to everyone. Assets that fail with no precursor, or are cheap enough to run to failure, rarely justify the effort — a serious assessment will tell you that to your face instead of selling you coverage.
How Atherya Implements Predictive Maintenance Analytics
Atherya was built as the opposite of the four sells, point by point.
Against "instrument first": Atherya starts by reading what your machines already write — OPC-UA, SCADA historians, PLC data, MES, ERP, WMS, CMMS, quality and shift records. In its reference onboarding at a rubber-moulding plant in northern Italy, it read six years of raw history — six million readings across 42 machines and five product families — before any hardware decision. From that history alone, 98 open operational questions were reduced to 7. No new sensors were installed to get there. Those are measured figures from one real plant; projections beyond them are scenarios, and we declare them as scenarios.
Against generic thresholds: Atherya learned 141 machine × recipe signatures in that same onboarding — not "presses like this usually behave like that," but this press, on this compound, against its own history. Context is in the model, not bolted on: the high-load recipe spike and the steady-state spike are different events to it, which is precisely what removes false alarms instead of manufacturing them. Cutting false alarms isn't a feature; it's the entry fee for technician trust.
Against the black-box score: every prediction carries its evidence — which signal, which baseline, which comparable historical event — with visible uncertainty attached. And when the data doesn't support a conclusion, the honest output is no conclusion: an RUL estimate is published only when the evidence can carry it, because a confident guess is worse than a declared unknown.
Against the orphan alert: this is the part the category skips entirely. Atherya plans the recommended maintenance window inside the production plan — the scheduling brain reserves it, reroutes the affected orders on real per-recipe capacity, and the proposal lands on a live board with its evidence, waiting for a signed human approval. Then the outcome loop measures what the ratified decision actually delivered, so the program's ROI is a measured number on your plant, not a slide. Prediction, plan, approval, outcome — one system, one audit trail.
All of it runs on-premise by default — the full brain on a small machine inside your plant, offline-first, your data never leaving the perimeter — with an optional cloud control plane if you want one. Hybrid is a choice, not a requirement. It coexists with SAP, Oracle, Infor, and Dynamics rather than asking you to rip anything out.
The Questions to Ask Any PdM Vendor
Bring these to every demo, including ours.
- "What can you tell me from my existing data, before I buy any hardware?" A vendor whose answer requires an instrumentation phase is telling you their model doesn't learn plants — it decorates sensors.
- "Show me one alert with its evidence." The signal, the machine's own baseline, the comparable event — live. A score without provenance is an opinion with a color scheme.
- "What's your false-alarm rate, and how is your confidence calibrated?" If they quote accuracy alone, ask what happens to technician trust after the third false positive. Watch for the flinch.
- "When your system predicts a failure, what happens to my production schedule?" If the answer is "the alert appears in the dashboard," you're buying a horoscope with an API.
- "Which of your quoted numbers were measured on plants like mine, and which are scenarios?" The honest vendor will split the list without hesitating. The other kind will repeat the 30–50% range and change the subject.
Implementation Roadmap: Pilot, Validate, Scale
The first 90 days are where the program earns or loses organizational trust. Treat them as a formal validation phase:
- Start with the data you have. A data-led assessment on historical records — machine logs, quality data, maintenance tickets, shift schedules — should produce named findings before anything is installed. If it can't, you've learned something valuable about the vendor at zero cost.
- Pick 3 to 5 critical assets with clear downtime cost and at least partial history, per the standard asset-selection guidance.
- Define success metrics up front: target lead time, acceptable false-alarm rate, and a money figure for downtime avoided. Written before the pilot, not reconstructed after.
- Validate against historical failures: would the model have caught past failures with enough lead time to act? Tune thresholds on that answer.
- Operationalize the full chain: alert → evidence → work order → schedule change → signed approval → measured outcome. If any link is missing, fix it before scaling — the chain, not the model, is the product.
- Scale with governance: monitor for model drift as seasons, recipes, and equipment age shift the data; re-validate quarterly. A model trained once and trusted forever is a threshold with extra steps.
Pro Tip: Resist the urge to perfect the model before showing results. A rough model that correctly predicted two real failures in 90 days builds more trust than a theoretically superior model still in development.
Most stalled programs stall for organizational reasons, not algorithmic ones — Deloitte's analysis points at cultural adoption and misaligned KPIs (maintenance measured on ticket-closure speed rather than downtime avoided) more often than model accuracy. The fix is the same everywhere: prove value on a narrow scope, keep a human signing every decision, and log everything.
What I'd Prioritize First
Don't start with the model, and don't start with a sensor catalog. Start with the question every vendor should be forced to answer: what does my existing data already know? Pick the two or three machines where downtime cost is undeniable, demand named findings from history alone, and judge the whole category on whether a prediction ever becomes a schedule change with a signature on it. The programs that stall are rarely the ones with mediocre models. They're the ones where a good prediction never made it into anyone's actual workflow — and that's a buying criterion, not bad luck.
— Atherya
Start With a Data-Led Assessment, Not a Blank Slate
Atherya is the practical alternative to building predictive maintenance from scratch: instead of months instrumenting sensors and training models on data you don't yet have, the Plant Profile assessment mines the historical records your plant already generates — and hands you machine-specific behavior signatures, hidden capacity, shift effects, and bottlenecks with evidence attached, before you commit to anything.
If your plant runs SAP, Oracle, Infor, or Dynamics, Atherya layers on top — no rip-and-replace. And if you want to see what predictions look like when they're wired to consequences, the Atherya AI Digital Shop-Floor Supervisor shows the full chain: evidence-backed alerts becoming signed, auditable work orders inside a live production plan, instead of sitting in a dashboard nobody checks. Send the export. Let your own history make the case.
Sources
- Using AI in predictive maintenance to forecast the future | Deloitte Global
- AI Predictive Maintenance 2026: A Manufacturing Guide | IIoT World
- Decision Framework for Predictive Maintenance Method Selection
- Data-driven AI framework for predictive maintenance (technical manuscript)
FAQ
What Is Predictive Maintenance Analytics?
Predictive maintenance analytics uses sensor and historical data with machine learning models to forecast equipment failures before they happen, rather than reacting to breakdowns or following a fixed calendar. Done properly, it compares each machine against its own learned baseline — per machine, per recipe — instead of generic thresholds, and attaches evidence and calibrated uncertainty to every prediction.
What Are the Main Types of Predictive Analytics Used in Maintenance?
Three core approaches: anomaly detection, which flags deviations from a machine's own normal and needs no labeled failures; fault classification, which names the specific failure mode but requires a labeled failure history most plants don't have; and prognostics, which estimates remaining useful life and demands both run-to-failure data and honest uncertainty estimates. Start with the first; earn your way to the third.
How Does Predictive Analytics Apply to Vehicle Maintenance?
The same principles apply to fleets: onboard sensors track engine temperature, vibration, and diagnostic codes to flag likely component failures before a breakdown. The same trust rules apply too — per-vehicle baselines beat fleet-average thresholds, and a prediction that doesn't change the service schedule changes nothing.
What Does a Predictive Maintenance Strategy Look Like in Practice?
A practical strategy starts before the pilot: a data-led assessment on records the plant already has, producing named findings with evidence. Then a narrow pilot on 3 to 5 high-cost assets, validation against historical failures within 90 days, and scaling only once predictions are wired to work orders, schedule changes, and signed approvals — with quarterly re-validation for drift.
How Much Does Predictive Maintenance Software Cost?
Pricing varies widely by platform, scope, and integration complexity, so there's no single industry figure worth quoting. Atherya's pricing for its platform and Plant Profile assessment is available directly from Atherya — and the engagement starts with the assessment, so the first thing you receive is evidence about your own plant, not a subscription.
Recommended
WHERE ATHERYA STANDS ON THIS
The problem on a shop floor is almost never a missing system. It is missing context.
Every plant we walk into already owns more data than it uses: years of machine history, orders, shifts, work orders, maintenance notes. What is missing is not another tool on top of the stack — it is a system that knows this plant. Which machine has run slightly hot since the day it was installed. Which deviation is normal on the night shift. Which alarm the team stopped reading two years ago, and why they were right to stop.
That is the difference between a model that scores signals and a system that has an operational memory. A generic threshold produces a false alarm every day on a machine born with a factory defect. Atherya learns each machine's own normal band first, so only movement beyond its band becomes an alert. Silence is a feature: the alarms that survive are the ones worth waking someone up for.
And an alert that stops at "anomaly detected" moves nothing. Atherya reasons on top of its memory: when this already happened, how similar it was, how it evolved, which action worked, which failure mode the FMEA connects it to. Then it does the part most tools leave to a spreadsheet — it proposes the maintenance window against real orders and real shifts, and replans when something changes. Nothing is ever applied on its own: every action waits for a person to sign it off, and every step leaves a signed, auditable trail.
That is the whole bet. Not one more dashboard to reconcile, not autonomy sold as a switch, but one brain that reads the data you already have — OPC-UA, SQL, MES, ERP, WMS, CMMS — before a single new sensor is installed, explains itself in the open, and gives the decision back to the people who run the plant.
What makes Atherya different
Most predictive maintenance tools score signals. Atherya builds an operational memory of the plant first, then reasons on top of it — with the evidence in plain sight and the decision left to a person.
Operational memory
Every event, anomaly, intervention and shift becomes shared memory. What was a log yesterday is experience tomorrow, and the model reads new signals against it.
Déjà Vu: it has seen this before
Not just "anomaly detected", but when it already happened, how similar it was, how it evolved and which action worked. The senior maintainer's memory, available to everyone.
Context that kills false alarms
Machine defects, weak points, how the crew actually works and the environment around the line. A deviation that is normal for that machine, that shift or that season stays quiet.
Living FMEA
FMEA, manuals and procedures become an active part of the reasoning: causes, effects, sensors and suggested actions are connected, instead of sitting in a document nobody opens.
Explainable, not magic
Every alert arrives with the signals involved, the comparable history, the failure mode and a confidence level. Data, interpretation and decision stay separate and verifiable.
It acts, with your sign-off
Atherya does not stop at the warning: it proposes the maintenance window against real orders and shifts, and replans when something changes. Nothing is applied until a person approves it.
On the data you already have
It works on PLC, SCADA, MES, ERP, maintenance records and feedback as they are — fragmented and legacy included. Sensors are added only where no existing signal carries the degradation.
One brain, not a maintenance silo
Maintenance, production and planning read the same operational state, so a predicted failure immediately becomes a scheduling question instead of a separate dashboard.
Related guides
YOU CAME HERE FOR A PROBLEM · HERE IS THE REST OF IT